
Temporal context
More frames, more gain
From one to seven frames, NOEMA climbs from 28.7% to 42.7% at a fixed size. The Context MLP grows with its input yet peaks at five frames.
Decoding naturalistic speech from fMRI with temporal modeling and multimodal alignment
Mesh adapted from “Human head” by ADAMA, CC BY 4.0
top-10 accuracy among 2,000 speech segments
of segments retrieved at rank one
points above the strongest baseline
parameters, 2.5× fewer than that baseline
01Model
fMRI is slow: it measures blood flow, which peaks seconds after the words that triggered it and blurs neighbouring words together. So NOEMA does not decode frames one at a time. It reads seven consecutive frames, about 15 seconds of brain activity, and predicts an embedding of what the participant heard just before the central one.
One shared linear layer maps each frame’s 20,484 cortical vertices to 4,096 features, frame by frame, keeping their order.
Two residual temporal convolutions, with dilations 1 and 2, let each position combine its neighbours.
Only the central position is projected into the 8,704-dimensional stimulus space. It sees all seven frames.
Hover or tap a unit to trace the frames it reads.
Each prediction is compared with a target built by three frozen encoders. Text and audio encoders summarise the last 10 seconds of speech, for context; a speech-recognition encoder covers only the last 2 seconds, for timing. Each embedding is normalised, then all three are concatenated.
Training is contrastive, as in CLIP: in each batch, a prediction must land closer to the segment actually heard than to all the others. At test time NOEMA sees only fMRI; the encoders just precompute the candidates.
normalised, then concatenated
8,704-dimensional target
NOEMA fits on one screen: here is its complete PyTorch definition, from the paper’s appendix. Train it on Cephalonauts One, streamed from Hugging Face, or hand the prompt to your coding agent and let it set things up for you.
The model
import torch.nn as nn


class TCNblock(nn.Module):
    def __init__(self, hidden_dim, dilation):
        super().__init__()
        self.layers = nn.Sequential(
            nn.Conv1d(hidden_dim, hidden_dim, kernel_size=3,
                      padding=dilation, dilation=dilation),
            nn.GELU(),
            nn.Conv1d(hidden_dim, hidden_dim, kernel_size=1),
        )
        self.norm = nn.LayerNorm(hidden_dim)

    def forward(self, x):
        # x: (batch, frames, hidden_dim)
        return self.norm(
            x + self.layers(x.transpose(1, 2)).transpose(1, 2)
        )


class NOEMA(nn.Module):
    def __init__(self, input_dim, output_dim=8704,
                 hidden_dim=4096, dropout=0.7):
        super().__init__()
        self.spatial = nn.Sequential(
            nn.Linear(input_dim, hidden_dim),
            nn.GELU(),
            nn.Dropout(dropout),
        )
        self.temporal = nn.Sequential(
            TCNblock(hidden_dim, dilation=1),
            TCNblock(hidden_dim, dilation=2),
        )
        self.output = nn.Linear(hidden_dim, output_dim)

    def forward(self, x):
        # x: (batch, frames, input_dim)
        x = self.temporal(self.spatial(x))
        # project the central frame
return self.output(x[:, x.shape[1] // 2])Ask your agent
Read the NOEMA page [1] and explore the Cephalonauts One dataset [2]. Let’s implement NOEMA, train it on one participant and check its top-10@2000 accuracy on the held-out session! [1] https:// karavela.ai/ en/ research/ noema [2] https:/ / huggingface.co/ datasets/ karavela/ cephalonauts_one
02Results
Every decoder is trained per participant and scored on held-out sessions, whose speech it never heard, by ranking about 2,000 candidate segments. NOEMA puts the right one in its top 10 for 42.7% of queries on Cephalonauts One and 43.6% on LeBel, against 0.5% by chance. It also beats the Context MLP, which sees the same seven frames with 2.5 times more parameters: the gain comes from how frames are combined, not from more input.
How retrieval is scoredHow often the heard segment ranks among the top 10 of about 2,000 candidates. Higher is better. Cephalonauts One: 3 participants, 30 hours each of French podcasts.
Bars: mean of 3 participants · Dots: each participant, mean of 5 folds
Controlled ablations, each retraining the decoders from scratch, isolate NOEMA’s two ingredients: temporal structure and complementary targets.
Temporal context
From one to seven frames, NOEMA climbs from 28.7% to 42.7% at a fixed size. The Context MLP grows with its input yet peaks at five frames.
Stimulus targets
Adding audio, then speech, to a text-only target helps every decoder for every participant, NOEMA most: from 27.6% to 42.7%.
Frame order · Cephalonauts One
Shuffle all windows the same way and retrain: the Context MLP just relearns its weights, while NOEMA loses 4.3 points. Its convolutions rely on frames being in chronological order.
Top-10@2000 accuracy, mean of 3 participants over 5 folds each.
A practical decoder must pick from an open-ended pool. We added up to 8,494 ten-second segments from 50 other episodes of the same podcast, absent from the dataset, to each test set of about 2,000, without retraining. The heard segment slips by 66 places for NOEMA, against 112 for the Context MLP and 191 for the MLP, and stays in NOEMA’s top 0.8% at the median.
Cephalonauts One · mean of 3 participants over 5 folds
Integrated-gradient maps show which inputs NOEMA’s predictions are most sensitive to. Sensitivity peaks at the central frame and, across the cortex, concentrates in lateral temporal and frontal regions consistent with the language network, though the model was given no prior about where language is processed.
These maps describe the model’s sensitivity, not a causal role of these regions. Nor do they show the left-hemisphere bias of language, which may take larger models to recover.
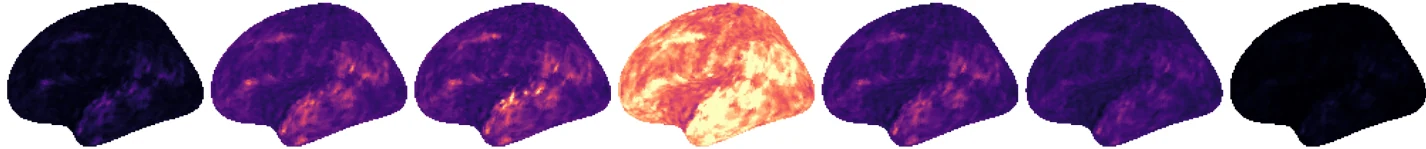 Right
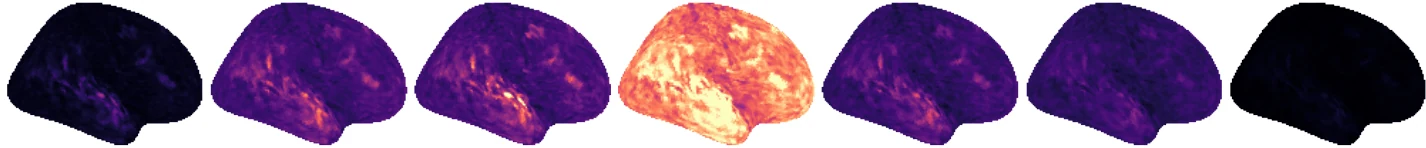 Time (s)−6.2−4.2−2.10+2.1+4.2+6.2
Six participants across two datasets; new people and tasks are untested. Sharing NOEMA across participants is the natural next step.
Picking from a finite set, even an extended one, is not open-ended reconstruction. Guiding text generation with NOEMA’s predictions is a promising direction.
Seven frames is set by the architecture, not tuned. Whether context helps through the delayed blood-flow response or the structure of speech is still open.
@misc{caris2026noema, title = {Decoding naturalistic speech from {fMRI} with temporal modeling and multimodal alignment}, author = {Caris, Corentin and Jalouzot, Louis and Rajabi, Nona and Ilinca, G{\'e}raud and Hassayoune, Ahmed and Muminov, Asilbek and Delebarre, Thadd{\'e}e and Fonteneau, Clara and Maussion, Charles and Thirion, Bertrand and Thual, Alexis and Collas, Antoine}, year = {2026}, note = {Preprint}}
Train it on Cephalonauts One, read the model code, then try to beat it. Share what you find with us and other researchers on Discord.